Judge an AI workflow by the state it leaves in your systems, not by how confident its message sounds.
Sponsored content from SourceX
Picture an AI demo that goes beautifully. The assistant reads the customer’s message, apologizes warmly and confirms the refund has been processed.
Then someone opens the finance system. There’s no refund. Or there is one, issued without the approval your policy requires.
Either way, the most polished part of the demo was the least important. The message was never the job. The job was a correct, authorized change in a real system.
That’s why AI workflow evaluation data has to measure more than words. It needs to connect the request, the context available at the time, the steps the worker was allowed to take and the state of the system afterward. Years of ordinary business records can supply exactly that, if they’re handled with care.
THE SHORT VERSION
- A fluent reply proves nothing. Evaluate the action, the authorization and the system state the AI leaves behind.
- Label outcomes separately: wrong decision, failed execution, unauthorized action and a correct decision to stop.
- Historical business records can make strong test cases if they show what was known at the decision point and the company has the rights to use them.

A confident reply and a completed task are not the same thing. Evaluation should check the system the AI touched.
Why is a polished answer the wrong thing to measure?
A transcript can look successful even when the underlying task is incomplete. If a reviewer scores only the reply, the evaluation may miss a failed transaction or a missing approval.
The fix is to write down what success means before you test anything. For a refund workflow, that could be: the order was verified, eligibility was checked, approval was obtained where required and the transaction was recorded. Some cases should end in an escalation, not a payment.
Researchers have built benchmarks around this idea. The original tau-bench work evaluates agents in policy-governed conversations by checking the final database state, which neatly separates what an agent says from the work its actions complete.
What does good AI workflow evaluation data look like?
Each test case should let you answer four questions:
- What did the worker know when the decision was made?
- Which actions were they authorized to take?
- What did the correct outcome look like in the system?
- Where should the case have stopped or been escalated?
Watch the timing. A closure note might reveal the answer. A later correction might overwrite a mistaken status. A policy update might change what the right action would have been. If that later information leaks into the starting context, every decision looks obvious and the test stops testing anything.
The message was never the job. The job was a correct, authorized change in a real system.
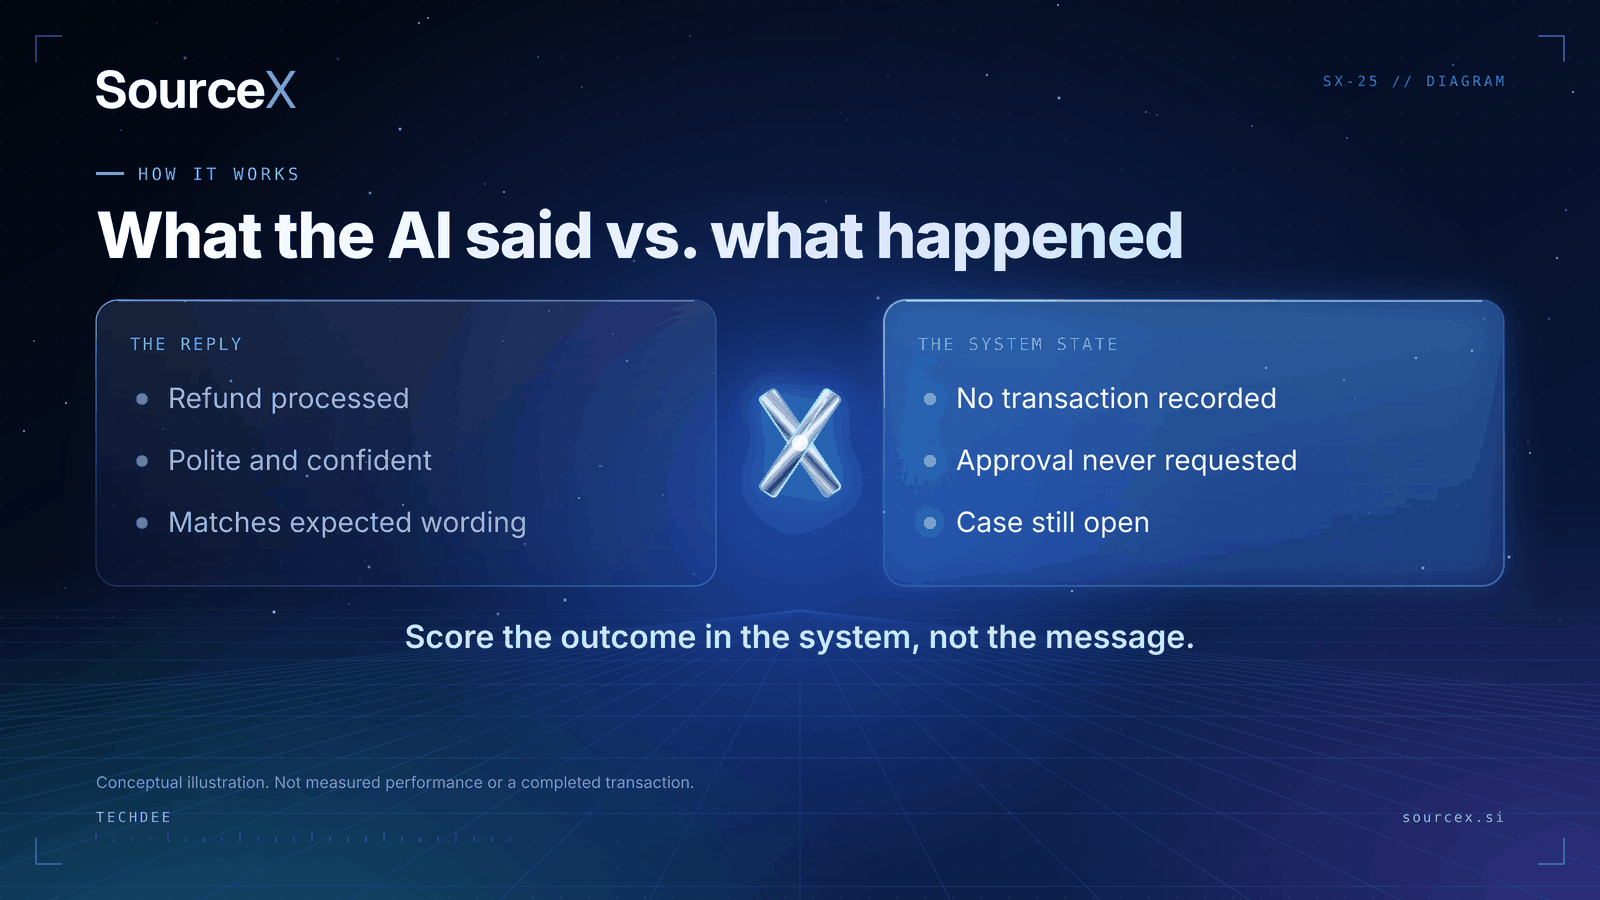
Illustrative example: an assistant reports success while the system of record shows otherwise. Not a real incident.
How should you score an AI agent’s outcomes?
A single success rate hides what needs fixing. Label these outcomes separately, including the case where stopping is correct:
- Wrong decision: the agent chose an action the policy didn’t support.
- Failed execution: the right action, done incompletely or incorrectly.
- Unauthorized action: the right outcome reached without the required approval.
- Correct stop: the agent paused because evidence was missing, which is a success.
An agent that escalates often may be appropriately cautious or simply incapable. Only the surrounding evidence can tell you which. Your evaluation set should also explain how examples were chosen, especially if the difficult exceptions are overrepresented.
Can historical business records become evaluation data?
Often, yes. Support, finance and CRM systems hold thousands of real cases with known outcomes. But they also hold customer-provided information, contractual restrictions and personal data alongside the company’s own work.
Start with an inventory that describes the workflow and its sources without exposing records. An authorized review can later define exclusions and preparation. De-identification can reduce exposure, but removing names alone does not establish anonymity. Assess residual identification risk for the actual release and recipients.
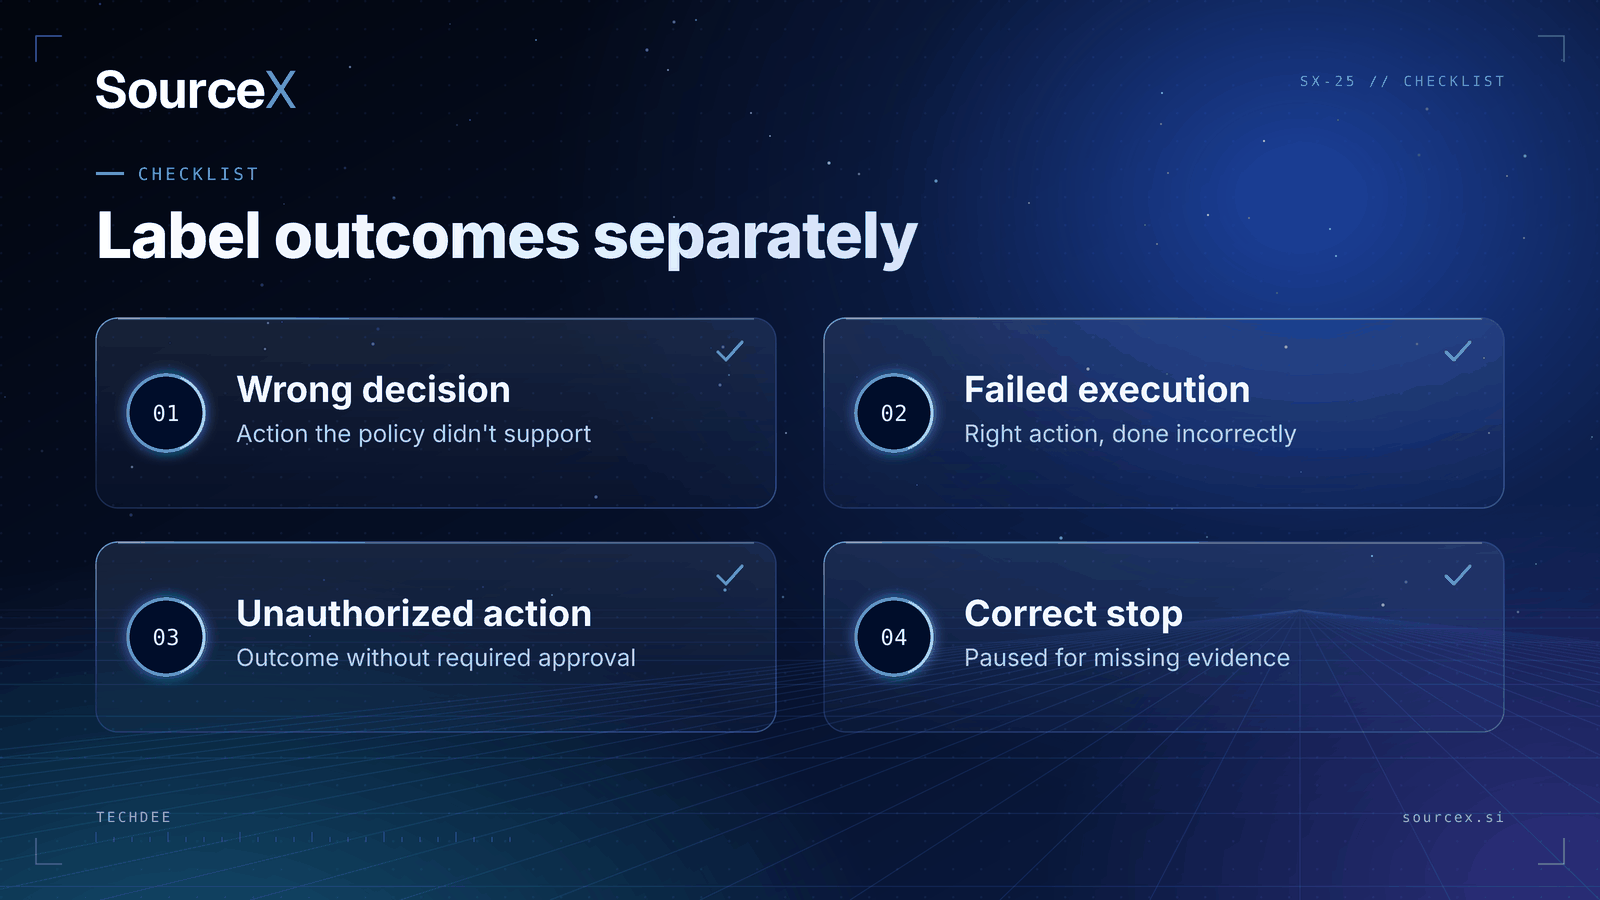
Four outcome types that a single success percentage would hide.
Could your workflow history be licensed?
Records of completed tasks can also interest AI developers building training and evaluation datasets. SourceX is one licensing route: it contracts with companies directly for approved business records and manages the agreement, preparation and payout. Historical cases still need an assessment of rights, completeness and suitability for the proposed task.
Its advertised maximum of $4 million applies to the largest enterprise datasets, not to a typical deal, and nothing is fixed until a Dataset Deal Confirmation is signed. SourceX’s sweet spot is businesses that peaked at 50 or more full-time staff and have operated for several years. Finding out where you stand takes a brief questionnaire, with nothing uploaded and nothing committed.
What should you ask in your next AI demo?
Ask the vendor to show you the system state after the task, not just the conversation. Ask which steps required authorization and how the demo enforced it. Then ask how the test case was built. Those three questions separate a tool that completes work from one that describes it convincingly.
Don’t grade the AI on what it says it did. Open the system and check.
Three demo questions that separate completed work from a convincing description of work.
Does your company preserve cases like these? An authorized leader can use SourceX‘s initial company fit check to explore licensing relevance. Share broad company information only; keep the evaluation records inside your systems at this stage.
About the founder
Noah Loul is a four-time founder and the founder and CEO of SourceX, which licenses business data directly from companies for AI training and evaluation. He previously founded B2B Rocket, acquired by Blackpearl Group. His work focuses on building permission-based data infrastructure for AI.